
Claude Fable 5.1
benchmark by benchmark
Every number below is quoted directly from Anthropic's own release page, browser-checked 02sep26 — not a third-party recap. AutomationBench is the one that matters if you run a business, not a lab.
Every Fable 5.1 benchmark against Fable 5 and Opus 5, quoted straight from Anthropic’s own release page — pricing and safeguard changes included. (8:54).youtube.com/watch?v=efhxZPpBXeI
AutomationBench (Zapier) — a real, multi-step business workflow, scored on whether the model finishes it without a human stepping in. Fable 5.1 nearly doubled Fable 5's clear rate, and beat Opus 5's 26.9%.
All nine benchmarks
| Benchmark | What it measures | Fable 5 | Opus 5 | Fable 5.1 |
|---|---|---|---|---|
| AutomationBench | Business workflows, end to end | 17.1% | 26.9% | 31.4% |
| Terminal-Bench-Science 0.1 | Agentic scientific research | 24.7% | 29.0% | 52.6% |
| Terminal-Bench 4.0 | Agentic coding | 42.0% | 52.3% | 55.8% |
| CursorBench 3.2.0 | Agentic coding | 70.5% | 70.0% | 73.4% |
| GDPval-AA v2 | Knowledge work / economic value | 1723 | 1824 | 1853 |
| OSWorld 2.0 (loose) | Computer use — task basically done | 72.9% | 75.4% | 77.9% |
| OSWorld 2.0 (strict) | Computer use — done cleanly | 36.1% | 39.6% | 41.7% |
| Humanity's Last Exam (no tools) | Multidisciplinary reasoning | 57.8% | 56.6% | 60.9% |
| Humanity's Last Exam (with tools) | Multidisciplinary reasoning | 63.8% | 63.6% | 65.0% |
GPT-5.6 Sol scores, where Anthropic published them: Terminal-Bench-Science 22.4% · Terminal-Bench 4.0 37.3% · CursorBench 67.2% · GDPval-AA 1711 · AutomationBench 19.6%.
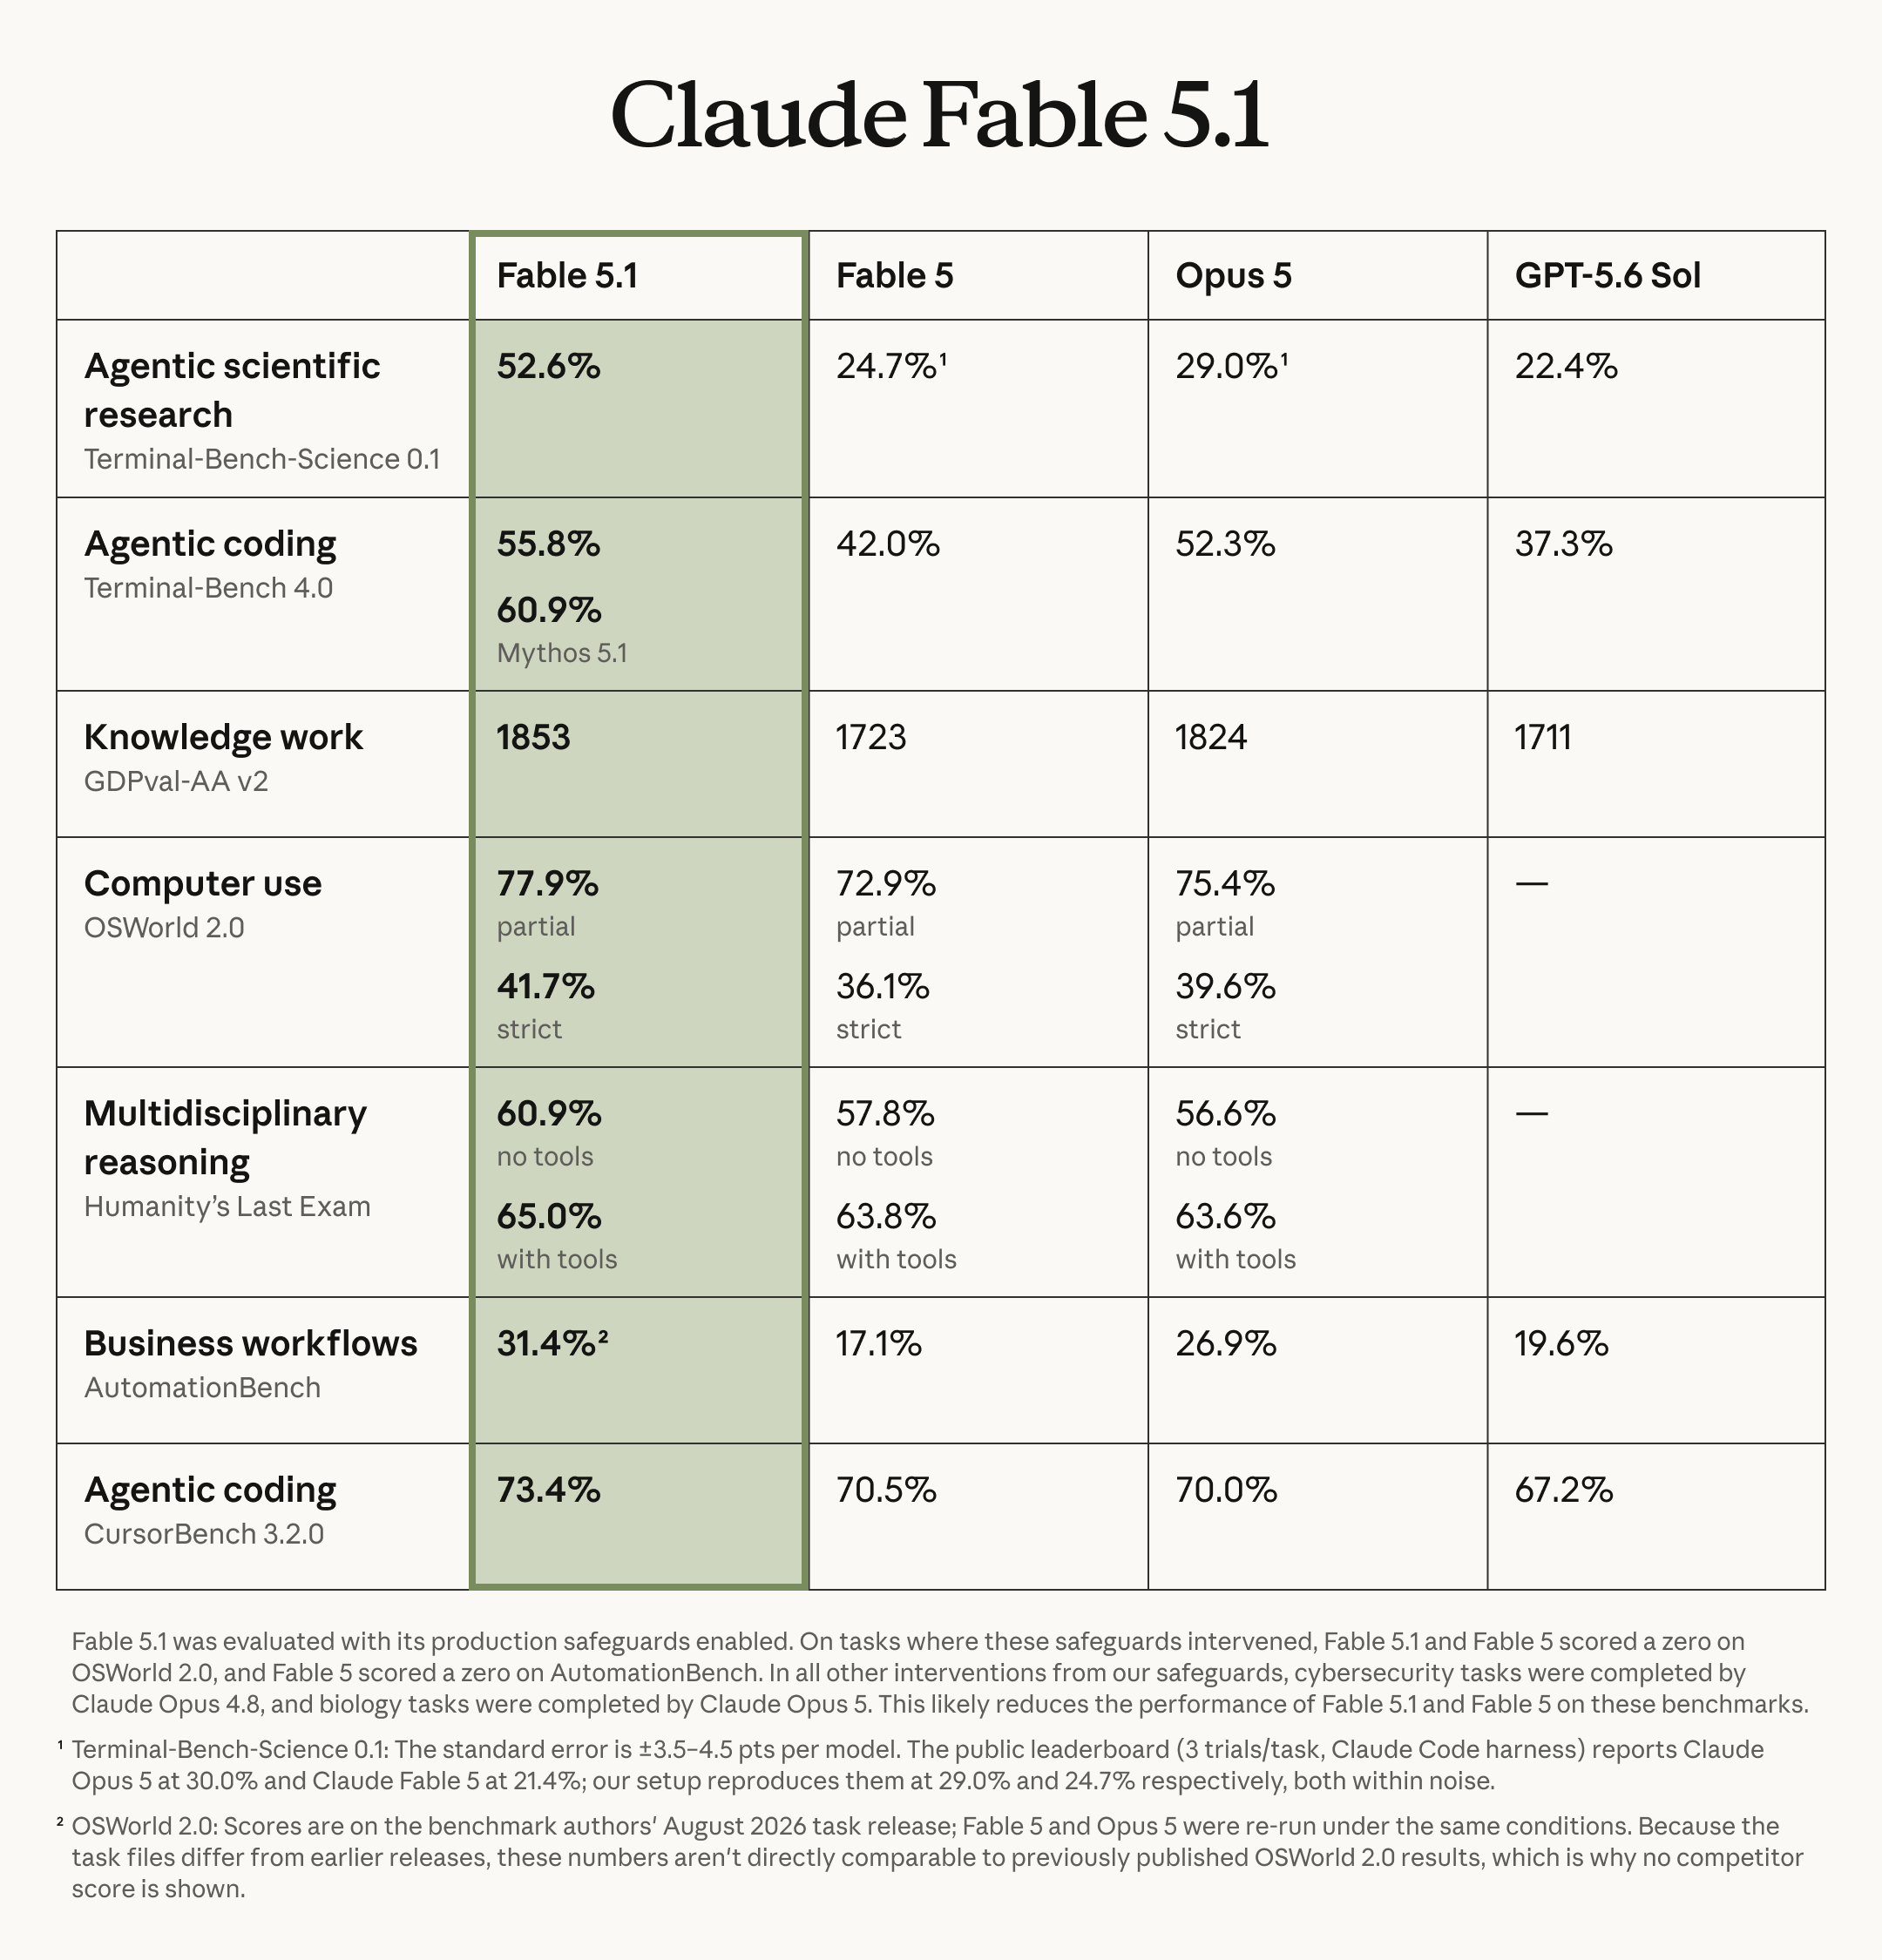
Anthropic's own table, posted to @claudeai. The table above restates it with GPT-5.6 Sol split out.
What it costs
Token pricing — unchanged
$10 / million input tokens
$50 / million output tokens
Same as Fable 5.
Cache reads −75%
Down to $0.25 / million tokens. Anthropic states this cuts typical workload cost ~25%, and up to ~45% for heavily agentic use.
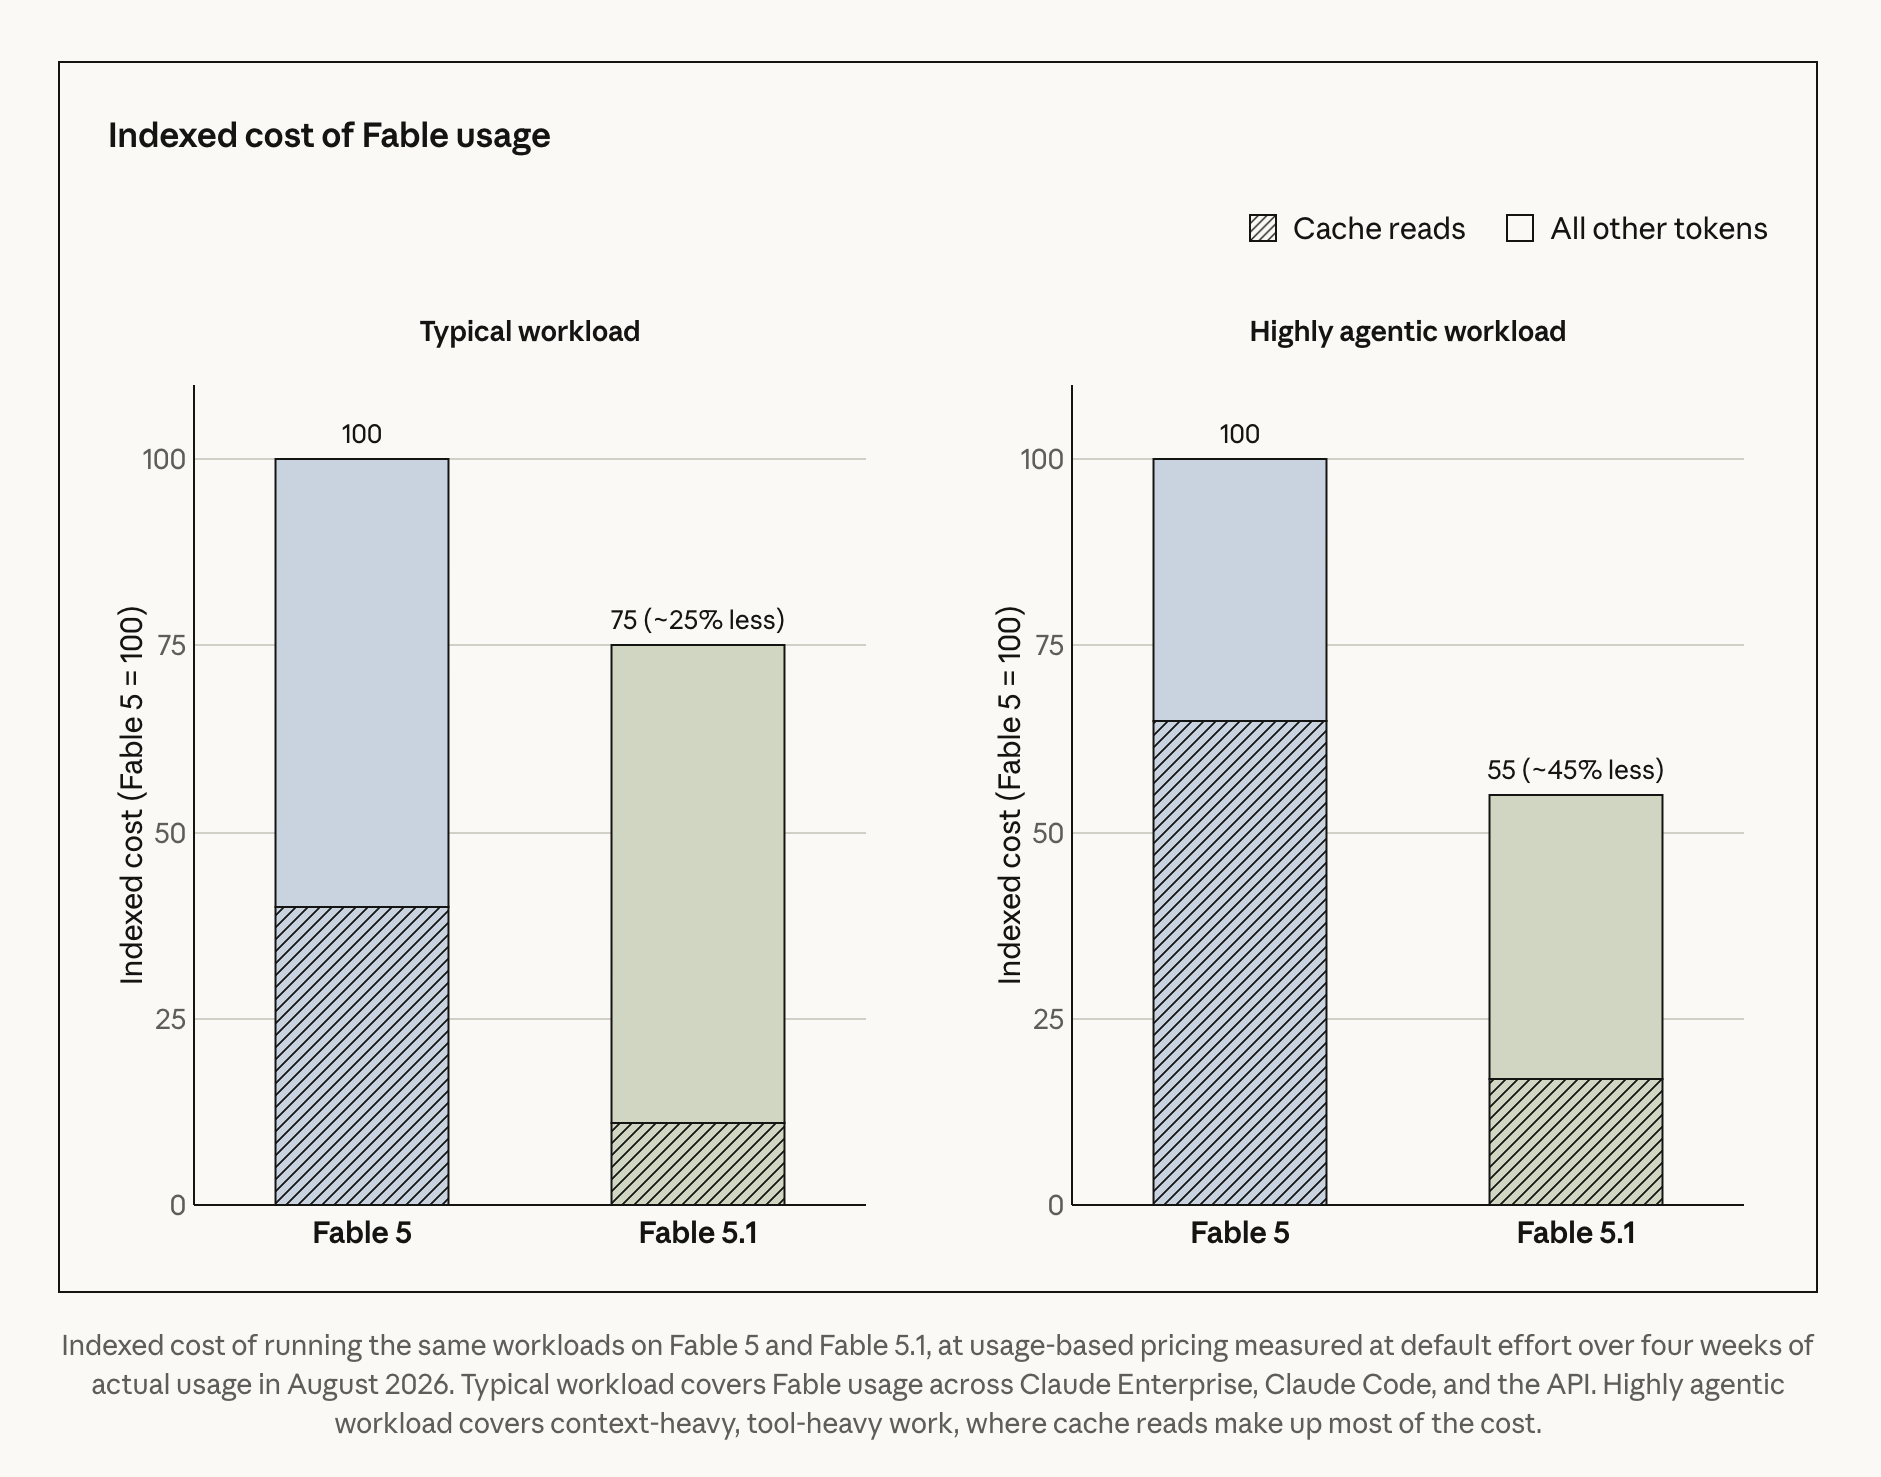
Where the ~25% and ~45% come from — cache reads are most of the bar on agentic work.
What a point of accuracy costs
The table above is every model at one setting. These are Fable 5.1 against Fable 5 at each effort level, plotted against what the task actually cost to run. The point is the shape: 5.1's curve sits above and to the left, so the same score comes cheaper, and the extra effort levels keep paying rather than flattening out.
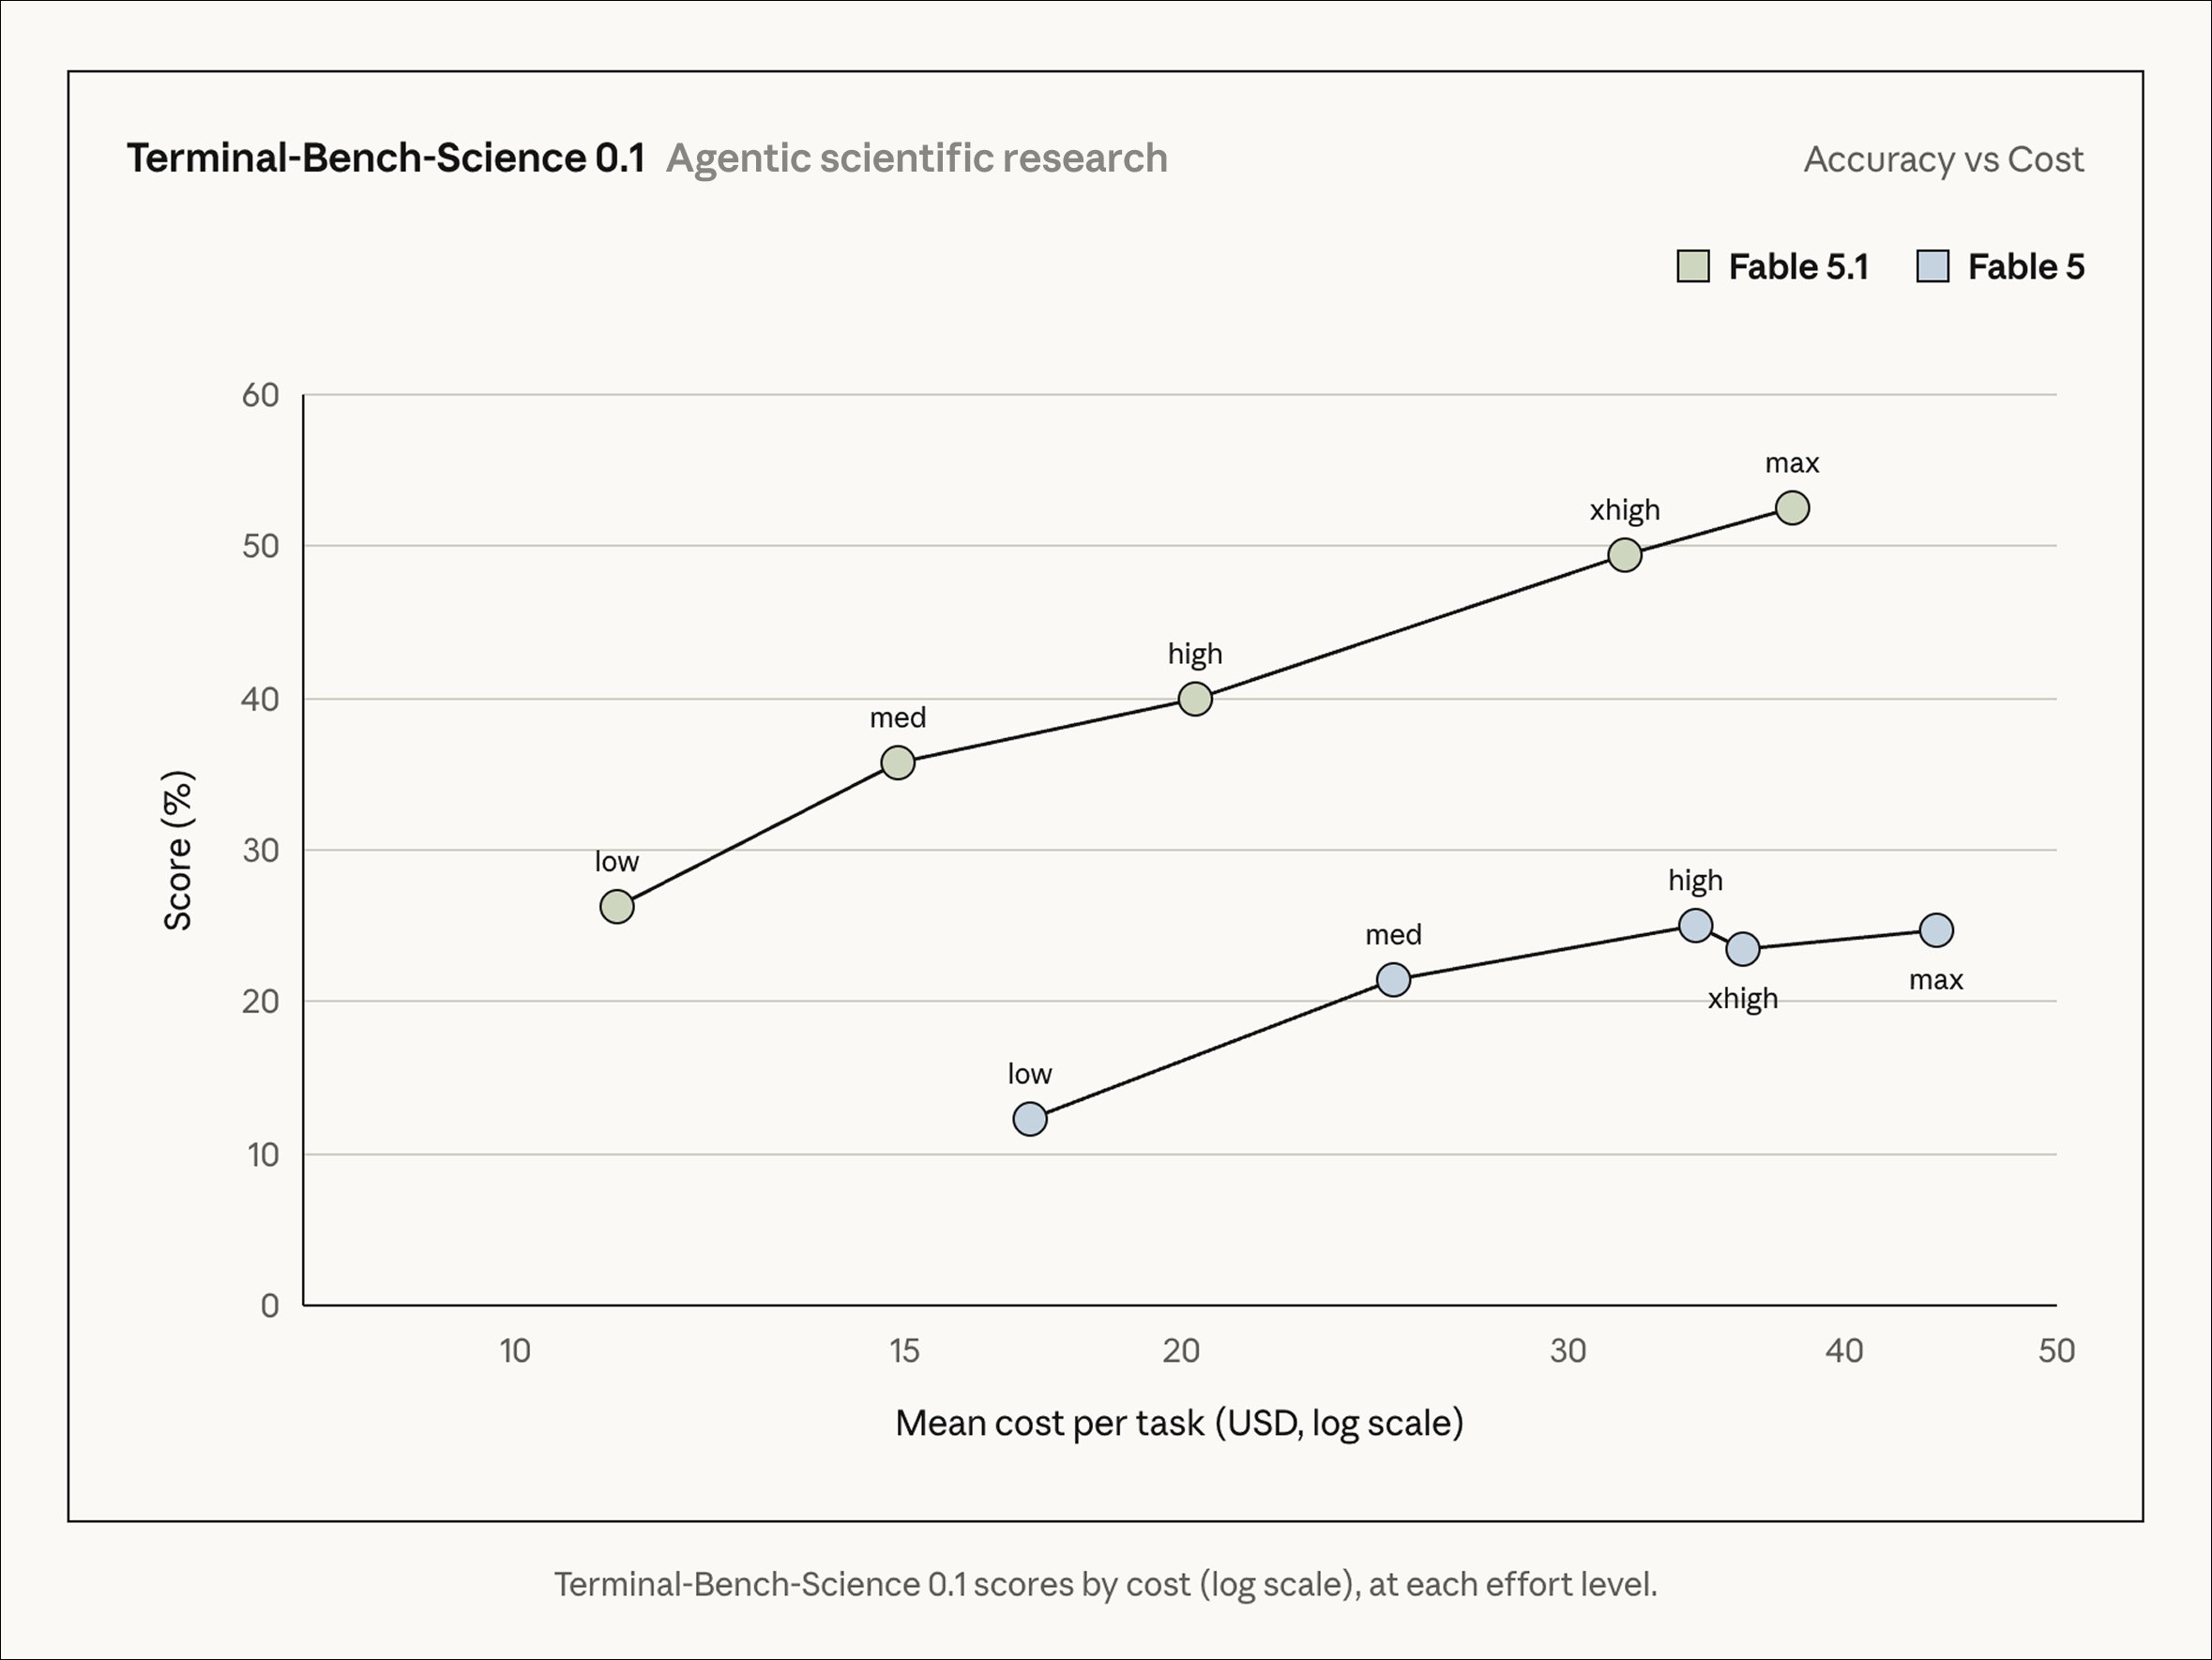
Terminal-Bench-Science 0.1 — agentic scientific research
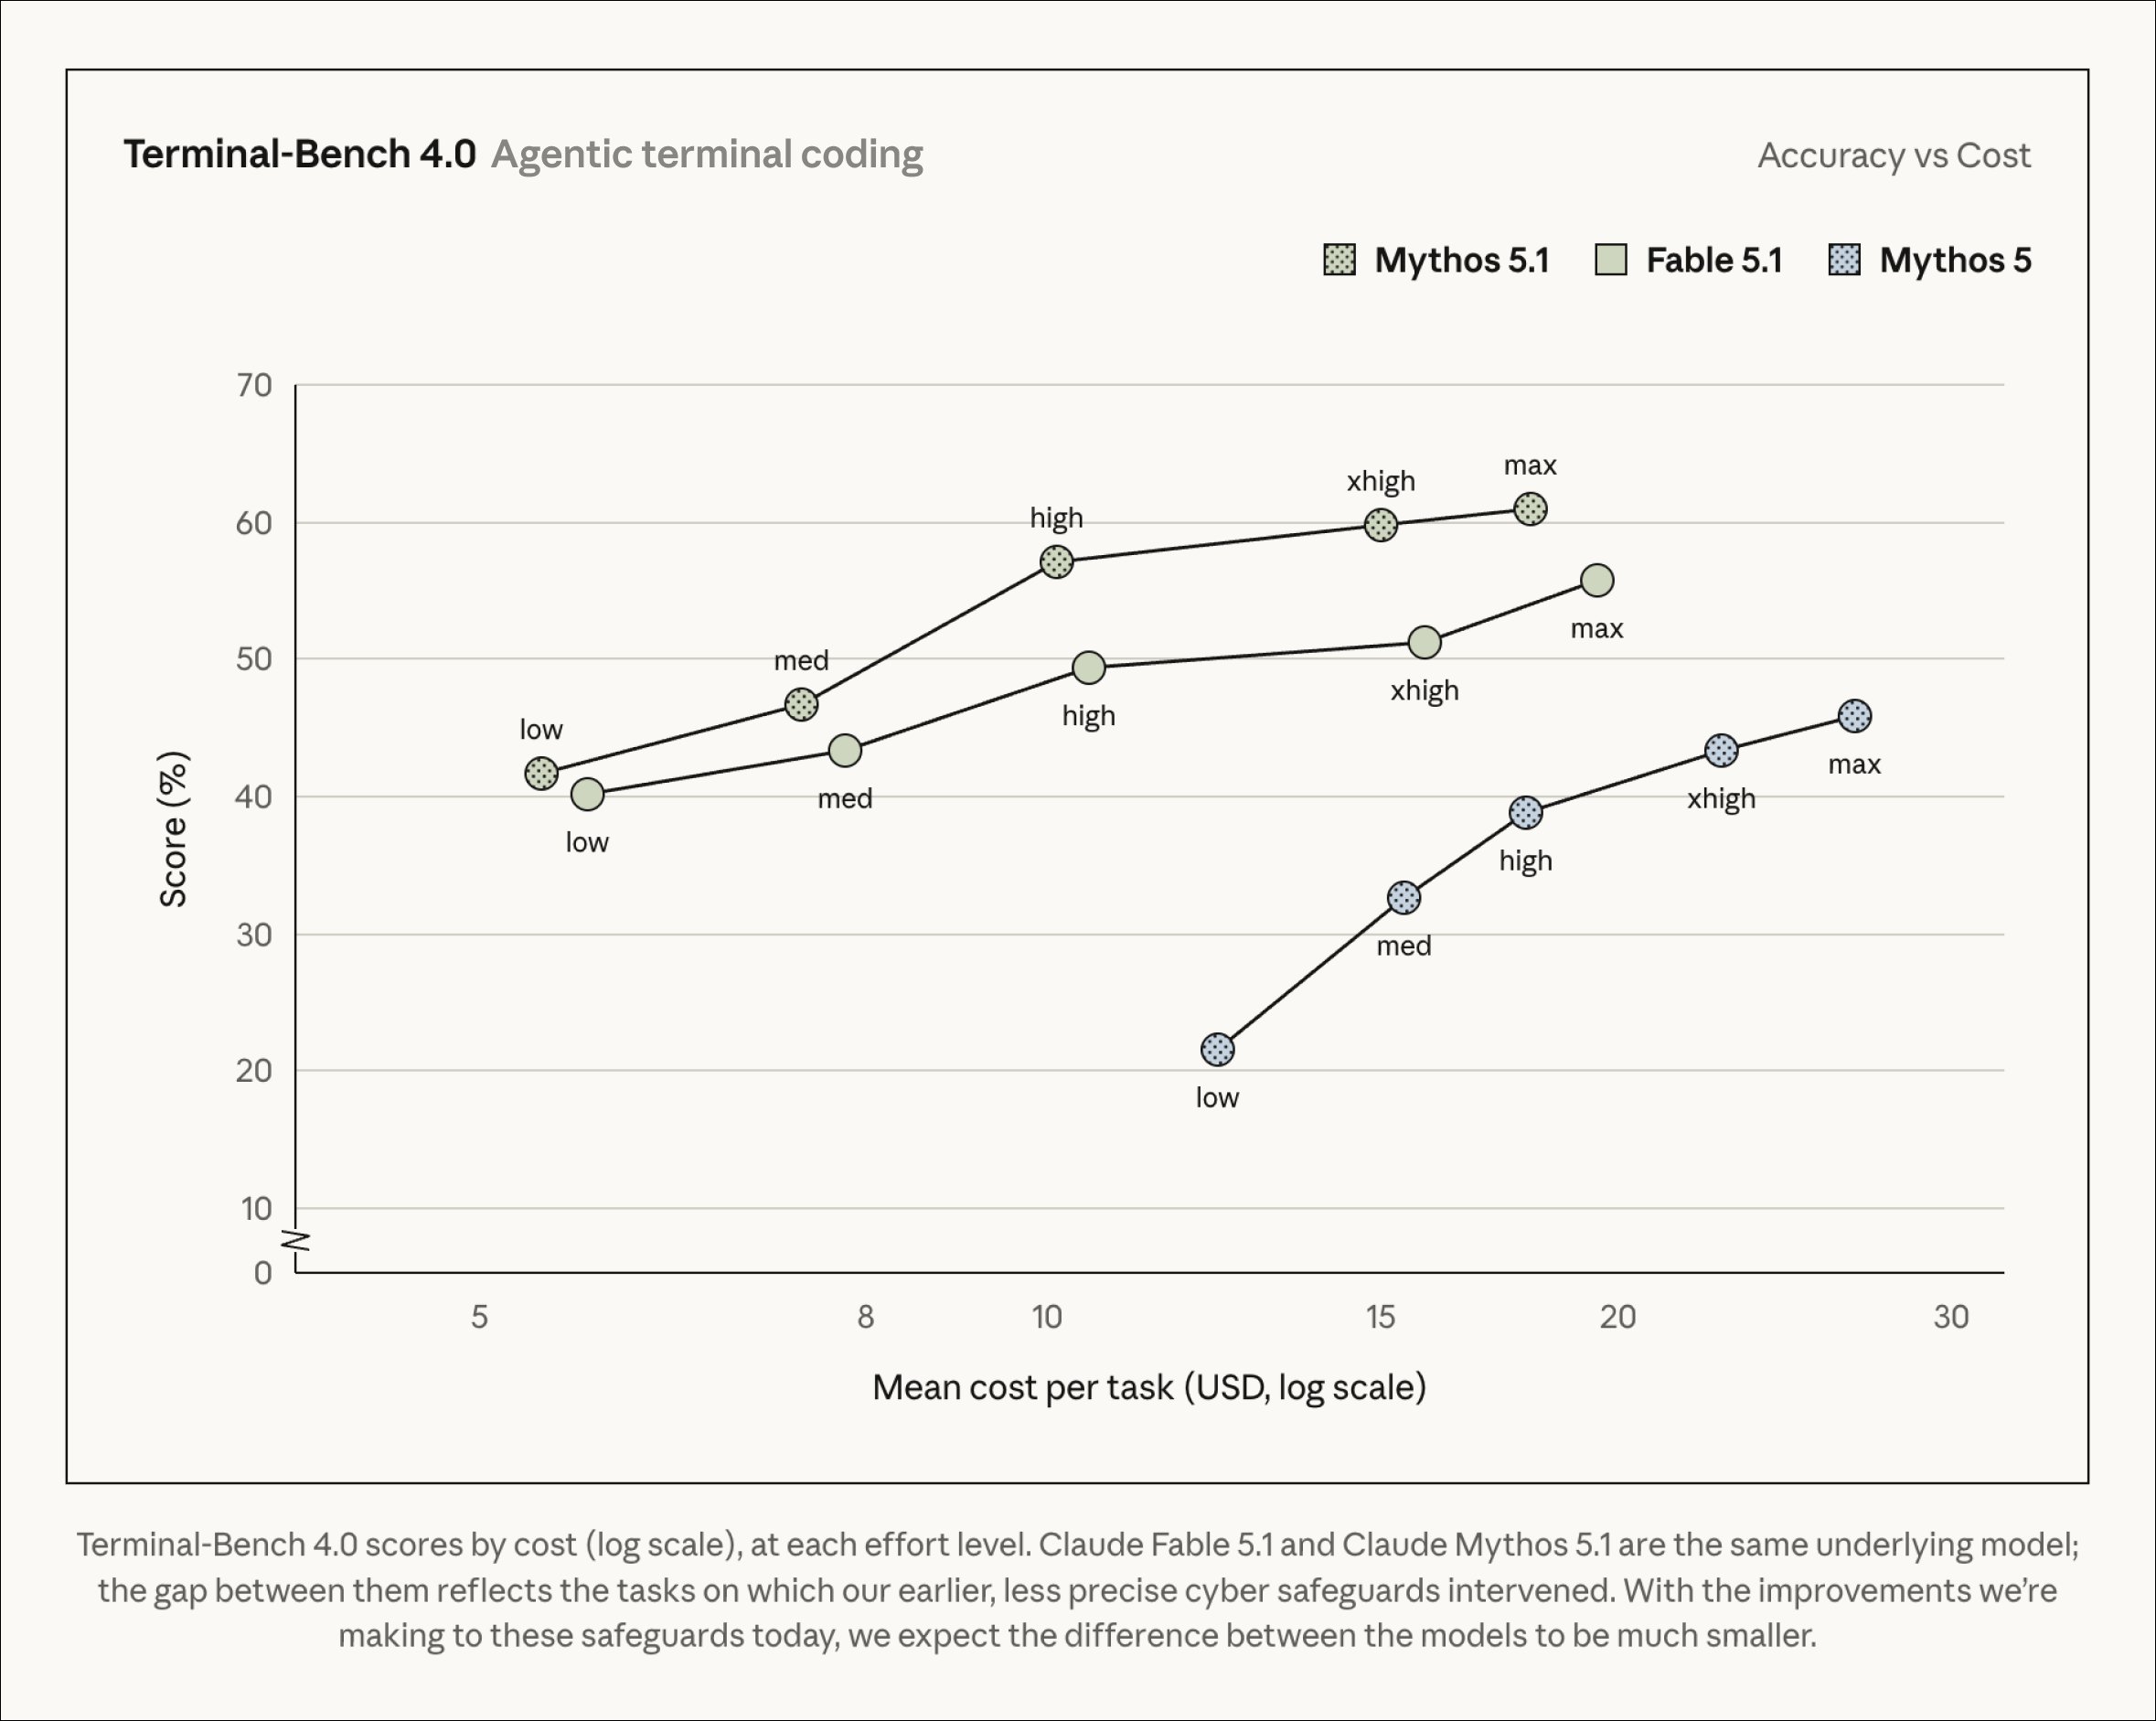
Terminal-Bench 4.0 — agentic terminal coding. Anthropic notes Fable 5.1 and Mythos 5.1 are the same underlying model; the gap between them is where the older cyber safeguards intervened.
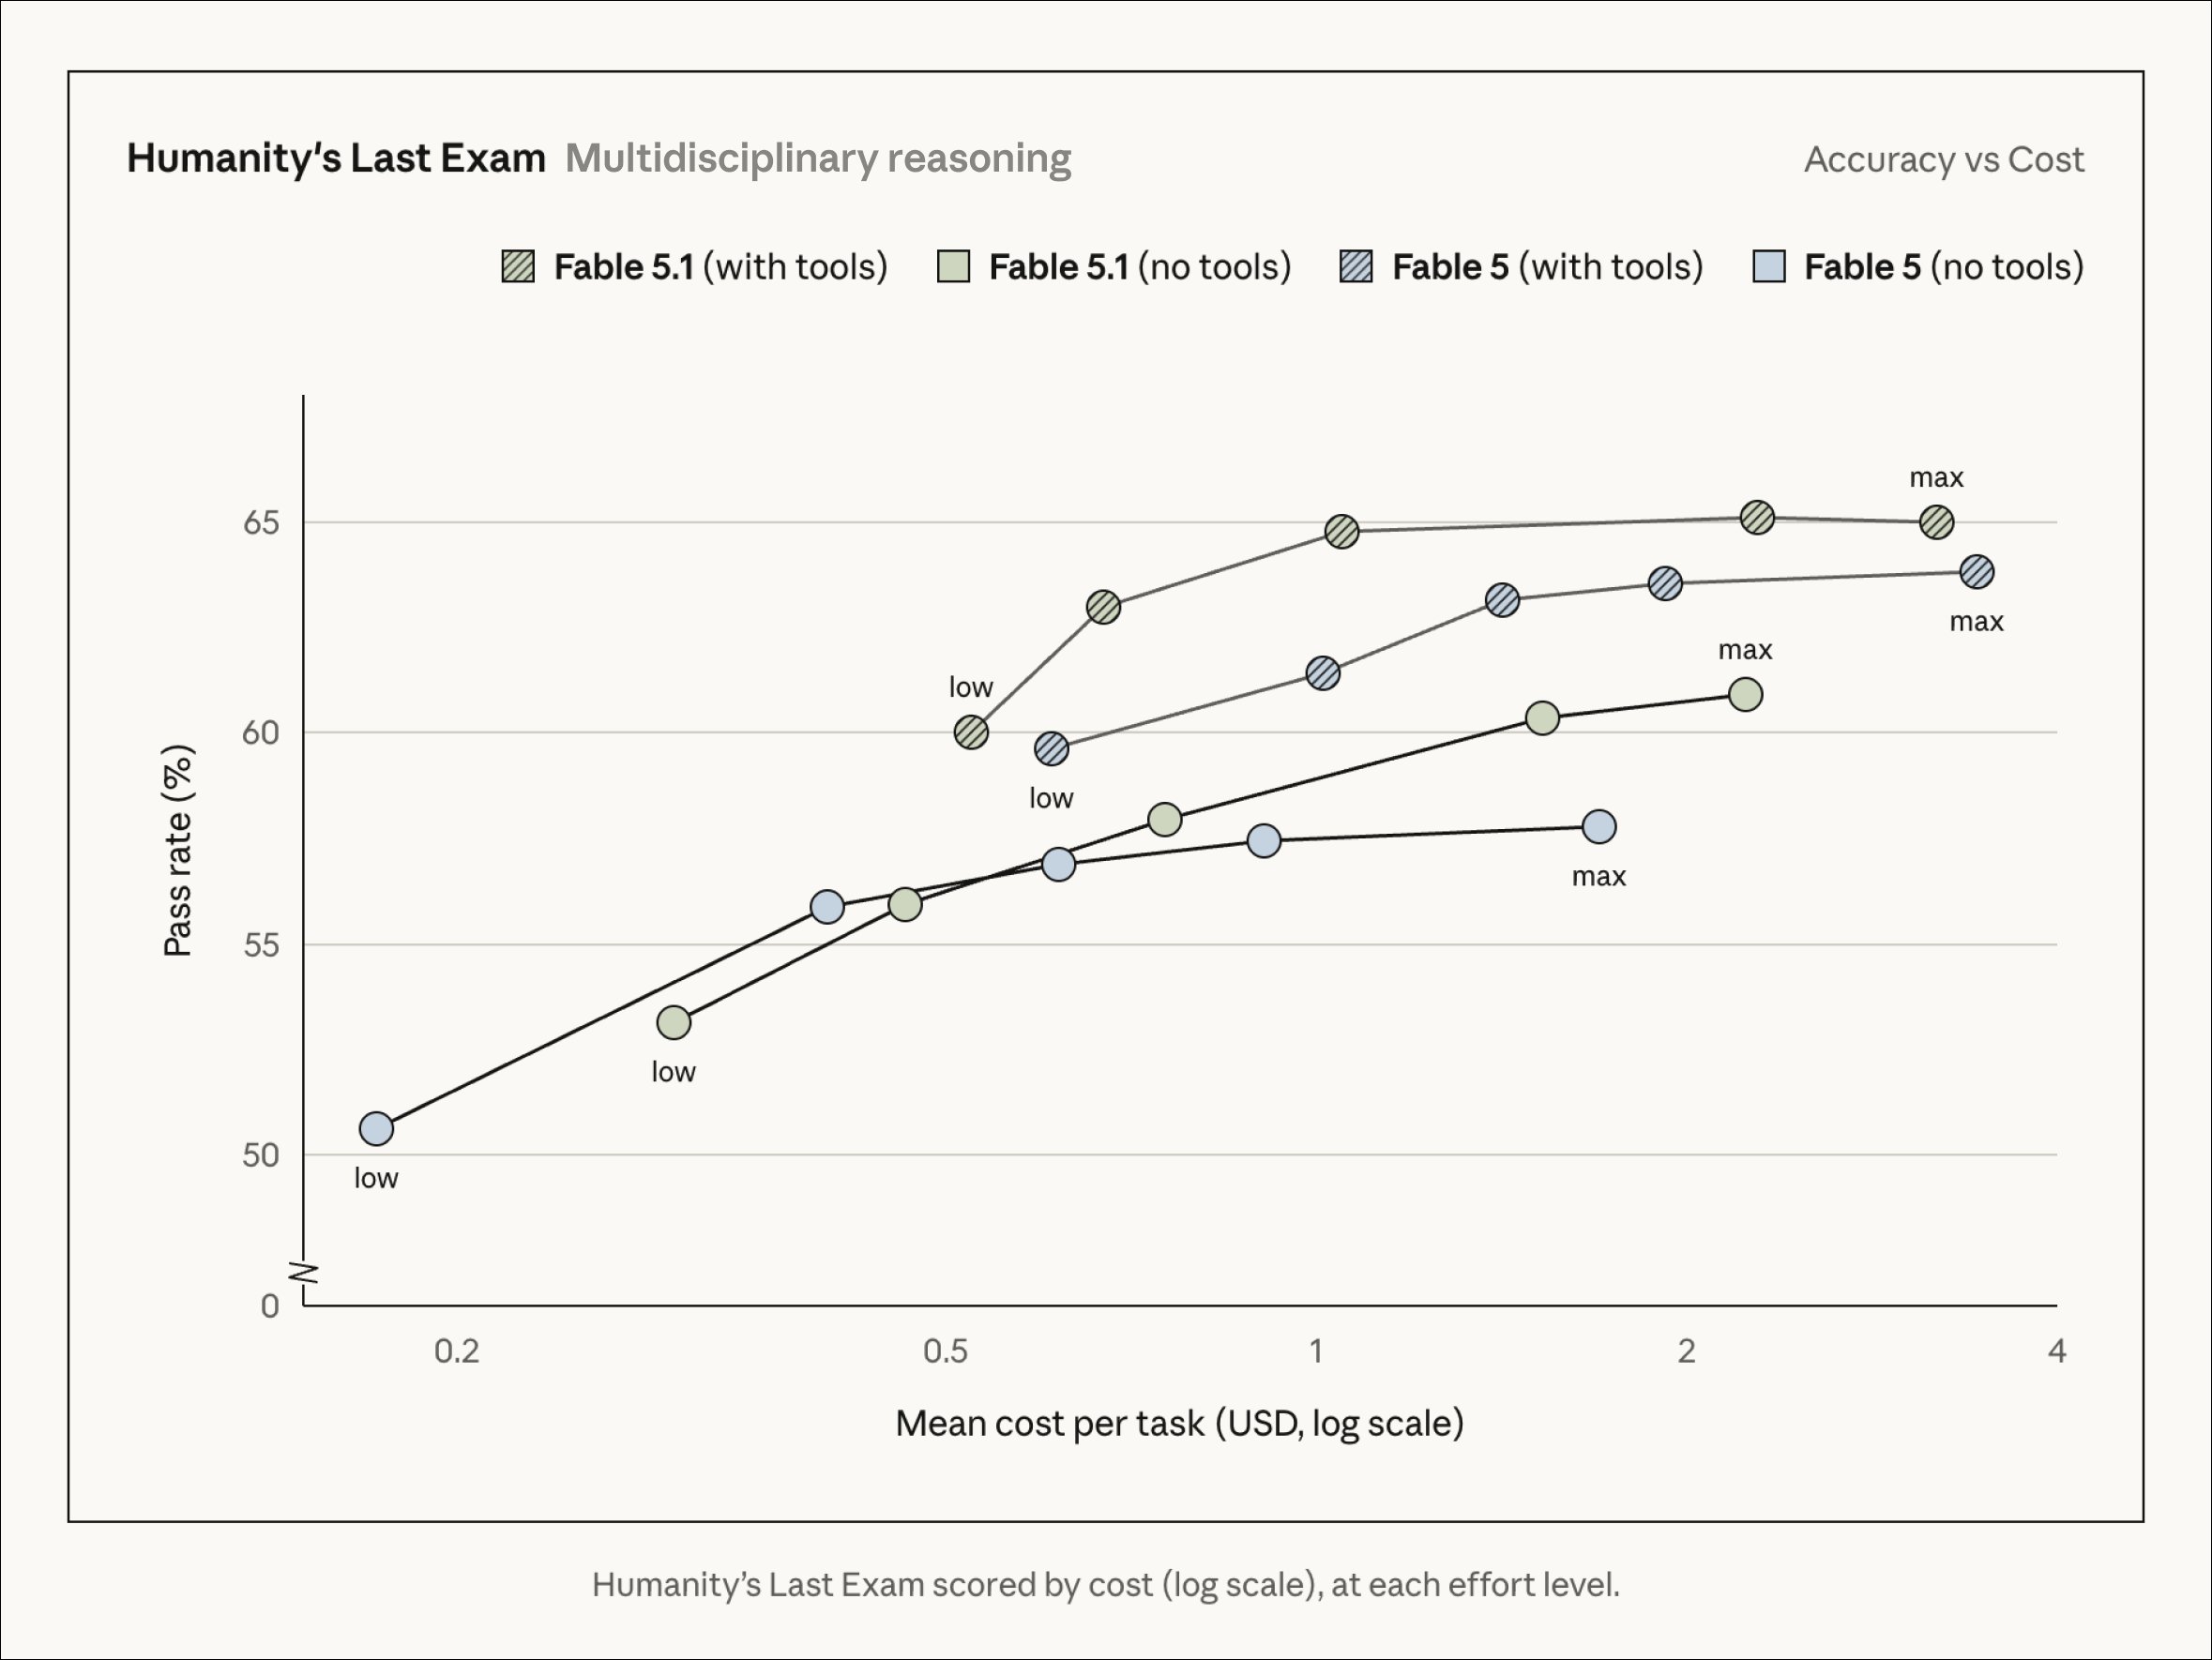
Humanity's Last Exam — multidisciplinary reasoning, with and without tools
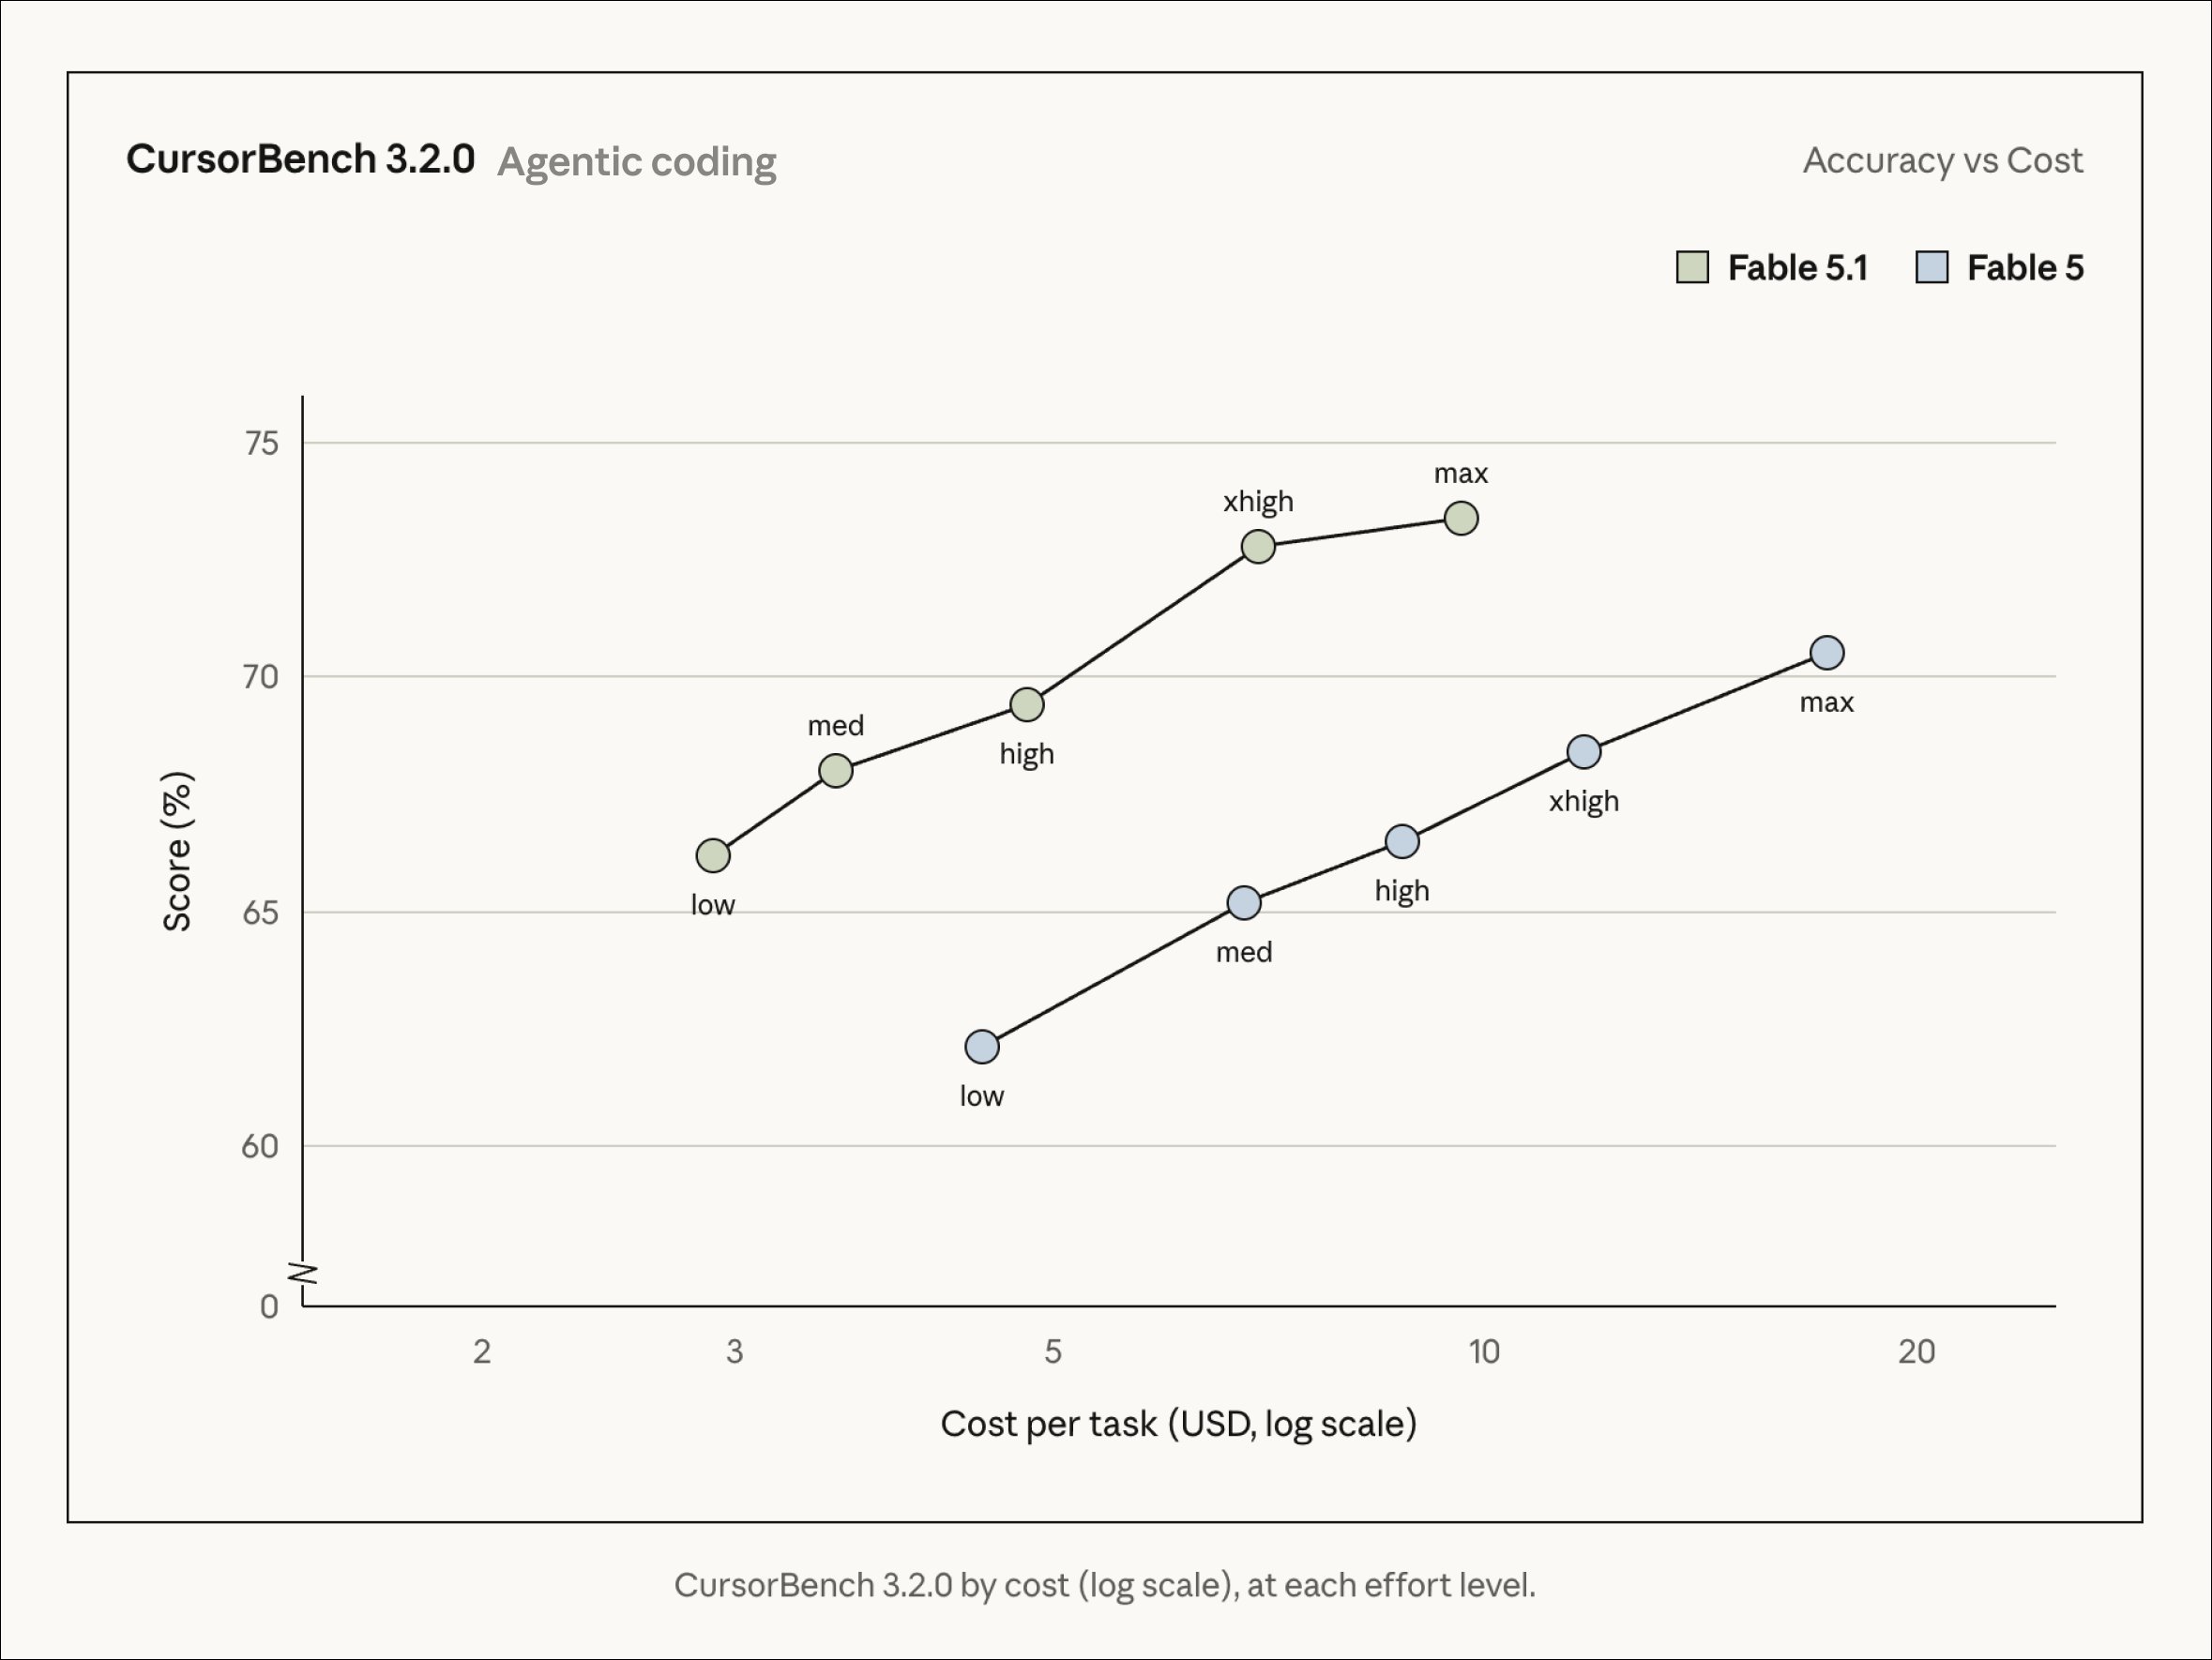
CursorBench 3.2.0 — agentic coding
All four charts posted to x.com/claudeai, 02sep26.
Safeguards
~60% fewer safety interventions per Claude Code session (cybersecurity). ~85% fewer false-positive refusals on benign biology questions.
Source: anthropic.com/claude-fable-and-mythos-5-1 · browser-verified 02sep26.